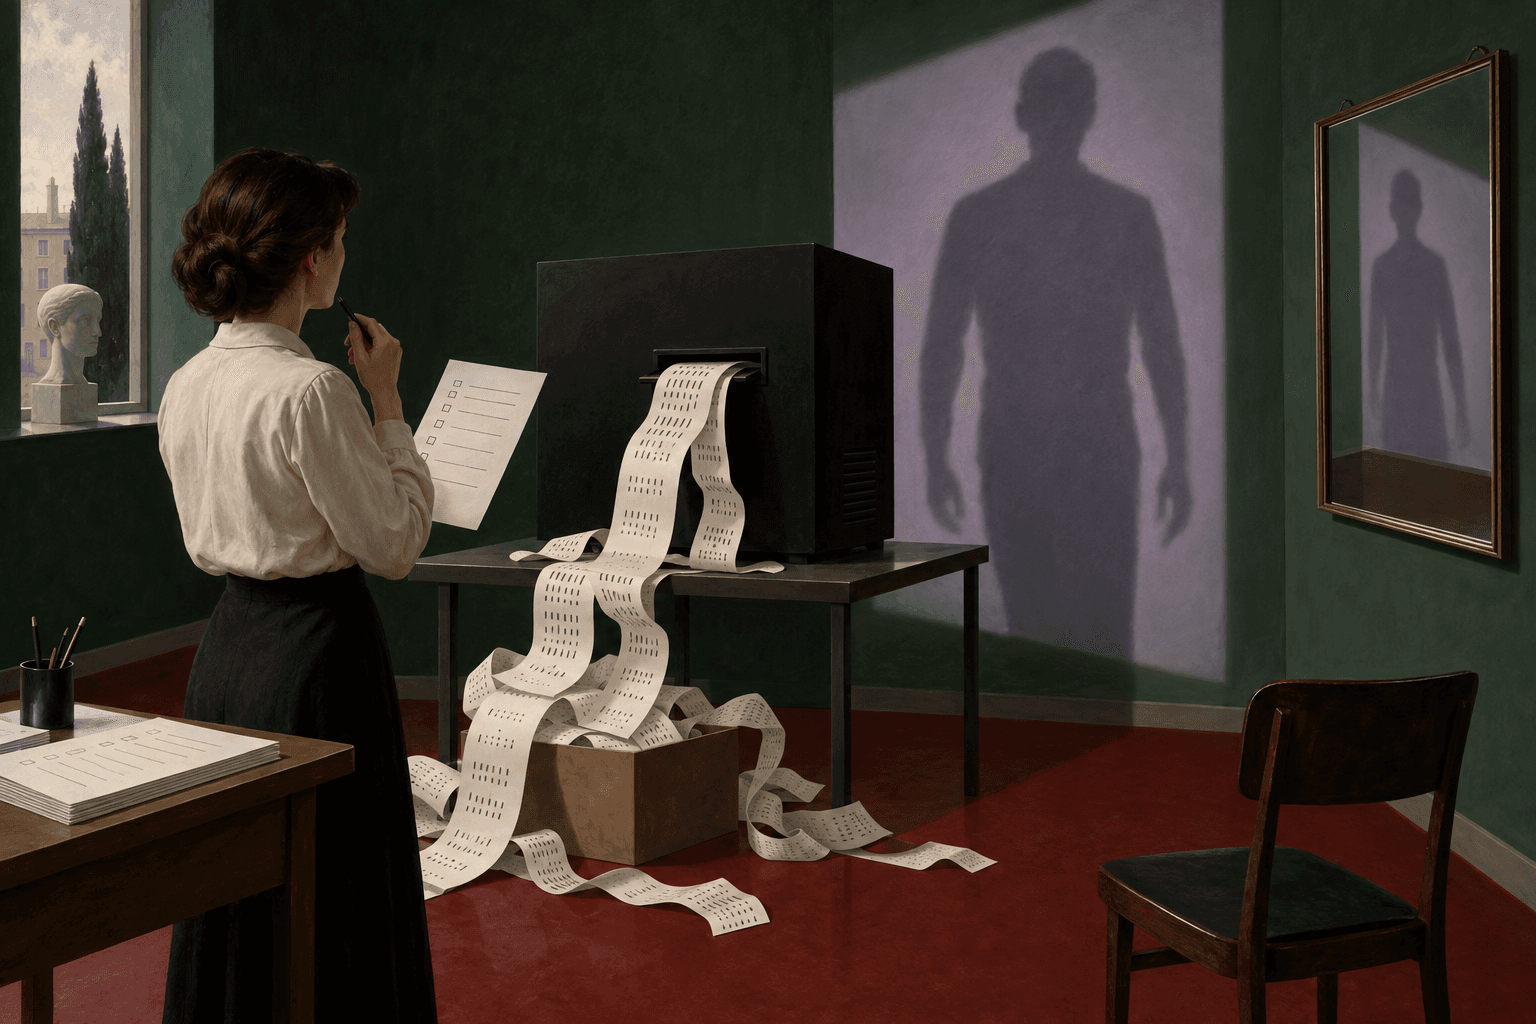
A chatbot completes a personality questionnaire and receives a confident score. The result looks familiar because the form was designed for people. But what did the test measure when its respondent was a system that predicts text?
A convincing answer is not yet a psychological finding
The questionnaire in the opening scene produces a score, but leaves open what that score measures. Zhicheng Lin opens his review with a related case from moral-judgment research: models appeared to have stable ethical preferences until researchers changed the labels of two choices or replaced a question mark with a period. Some answers reversed. The change in punctuation was not a change in moral principles. It exposed how easily the testing format could shape the result.
Psychologists have spent decades testing whether a score means what researchers claim it means in people. Giving the same questions to a system built to predict text does not carry that validation across automatically. It may generate a fluent answer because the wording activates familiar patterns, because it is following an instruction or because it has encountered similar examples in training. Lin calls a regularity mistaken for a genuine psychological phenomenon a measurement phantom.
The review is not an argument against using language models in research. It asks researchers to match the claim to the evidence. ‘This model produced these answers under these prompts’ describes an observation. ‘This model experiences anxiety’ makes a much stronger claim about an underlying state. Between them lies a chain of tests that the attractive score alone cannot supply.
The same model can play very different research roles
Lin separates using a model as a tool from studying the model itself. If a researcher asks it to classify interview texts, the immediate target is the texts. The practical tests concern accuracy, consistency and whether errors matter for the study. If the researcher instead asks whether the model has a personality trait, the target shifts to the system: its responses are now supposed to reveal a property of the model. That change demands evidence about what the questionnaire measures in this new setting.
The review describes a ladder of scientific claims. Describing a model's behavior under specified conditions is one step. Claiming it simulates a human population adds the need to reproduce relevant human patterns, including their variability, across meaningful changes in tasks and prompts. Claiming that the model explains human cognition goes further: similar outputs are insufficient unless the processes producing them illuminate human mechanisms. The same sentence generated by a chatbot can support different conclusions depending on the rung the study aims to climb.
This ladder helps without treating every study as a philosophical dispute about machine consciousness. A model may be a useful text-coding tool even when a claim that it has an enduring inner trait is unsupported. The evidentiary burden grows with the ambition of the interpretation, not with how human the answer sounds.
First ask whether the result is stable
Before asking what a score means, a researcher needs to know whether it can be reproduced. Lin distinguishes three kinds of reliability in plain terms: does the same test give a similar result again; do equivalent ways of asking produce comparable answers; and do several questions meant to measure one thing fit together? A questionnaire that calls a model anxious on Monday and calm on Tuesday under essentially identical conditions cannot support a strong account of an enduring trait.
The article shows why this is difficult with language models. Answer choices labeled A and B can yield different profiles from choices labeled 1 and 2; a reversed scale can change what looks like personality. Sampling settings alter how varied the output is. Earlier turns in a conversation shape later answers, and a model update can change the behavior of a system carrying the same commercial name. Reporting the exact model version, prompt, context and generation settings is part of the measurement, not a technical footnote.
Stability is necessary but not sufficient. A model can consistently agree with contradictory personality statements because training rewards agreeable language. It can reliably reproduce a stereotype from its training data. In both cases repeated scores might be highly consistent while the proposed psychological interpretation remains wrong. Reliability tells us whether there is a pattern to explain; it does not tell us what the pattern is.
Then ask what the test is measuring
A sound interpretation needs several kinds of evidence, not a single impressive example. Lin asks whether the questions cover the proposed concept rather than a tiny corner of it. One moral dilemma cannot stand for all moral reasoning. He also asks what process generates the answer. A correct response to a familiar theory-of-mind story might reflect a learned textual pattern rather than the way people infer another person's belief. The famous horse Clever Hans seemed to calculate but followed cues from his handler; the warning here is to investigate the source of success before naming the ability.
The internal structure of answers is another check. Questions intended to measure the same trait should relate to one another in a way the theory predicts. Human personality questionnaires often do not reproduce their expected factor patterns when applied directly to models. Yet the review also discusses more promising methods: analyzing values in free-form generated text or using concrete behavioral scenarios can reveal more coherent patterns. A failed human questionnaire therefore need not settle whether every computational analogue is impossible; it may show that the borrowed instrument is a poor fit.
Finally, a score should connect to other observations as expected. A model that calls itself reserved but writes outgoing dialogue raises a question about the meaning of the self-report. In one approach reviewed, a task designed around word associations predicted sentiment in generated text better than a human-style self-description. Lin's proposal is to build measures suited to computational systems and to test the interpretation that each measure can actually support.
A change in output is not automatically a causal explanation
Suppose a researcher changes one sentence in a prompt and the model gives a different answer. The new sentence may matter, but what did it change? Lin joins the psychology of measurement with the logic of experiments. The first asks whether the observed answer represents the proposed concept. The second asks whether the change can truly be attributed to the intended manipulation, rather than to another feature that changed at the same time. Both questions are needed when the output is used as a measurement and as an experimental result.
The paper describes a study that gave a supposed Chinese participant prompts in Chinese and a supposed American participant prompts in English. Any difference mixed the assigned identity with the language of the prompt. Another example concerns prices: when a product price changed, a model inferred that the whole market had changed as well, including competitors' prices. The model was not holding the background fixed as an experimenter expected. Explicitly listing every condition may solve one ambiguity but make those details unusually prominent and change the task again.
Researchers can improve these designs by varying formatting separately from substantive content, crossing language with assigned identity, documenting settings and testing more than one model version. The goal is not to make every response invariant. It is to know which changes are part of the phenomenon and which are artifacts of how the test was written.
The result may not travel beyond that exact prompt
Even a well-controlled finding can have narrow reach. If a model follows one version of a moral dilemma, will it follow another phrasing, a different task, another model family or a later release? Lin calls this a question of generalization. Some language models reproduce human responses in certain social games but fail in tasks that depend on independent variation across people, such as the wisdom-of-crowds effect. They are systems with shared parameters, not collections of separate human minds.
A simulated public-opinion survey may also resemble an average response while missing the range, intensity or changing views within the population. Good agreement with one benchmark should be reported as agreement with that benchmark, not as proof of a universal human simulator. A finding from one model or one population represented in the training data should not be silently extended to other models or less represented groups.
The same restraint applies to process claims. A chatbot can produce fluent descriptions of emotion without evidence that it has emotional awareness in the human sense. Similarity of output is a worthwhile fact, but an explanation of the mechanism requires different tests. That distinction is what stops an engaging demonstration from becoming an unsupported theory of minds, human or artificial.
Many answers from one model are not many people
The review ends with a statistical warning that is easy to overlook. A researcher can ask one model the same question a thousand times. Those answers may vary, but they share training history, parameters and system rules. Treating them as if a thousand independent people had responded makes the sample look stronger than it is and can create falsely narrow uncertainty estimates. In a long conversation, later replies are even less independent because the earlier ones form part of the context.
Cheap, rapid generation brings another temptation: trying many prompts and reporting only the one that produced an exciting effect. A result found after extensive undisclosed searching has a different evidentiary value from one predicted and tested in advance. Lin recommends transparent reporting, planned analyses and robustness checks, along with statistical methods suited to computational systems rather than copied uncritically from studies of people.
This is a practical editorial test for any headline about ‘AI psychology.’ Ask how many distinct models were studied, how many prompt formats were tried, whether a stable measure was established and what the analysis treated as an independent observation. A large count of generated sentences may conceal a very small count of genuinely independent systems.
Build the measure before naming the trait
Lin's dual-validity framework is demanding, but its order is simple. First establish that a test gives sufficiently stable results under conditions relevant to its use. Then assemble evidence that those results measure a defensible concept in a language model. Finally, if claiming cause and effect, design the comparison so prompt wording, model settings, versions and statistical choices do not supply an easier explanation. A stronger claim must clear every earlier step; a weaker but well-supported claim can still be valuable.
The constructive path is to design computational counterparts of psychological concepts and test them as carefully as any new instrument. A system's consistency, ability to solve a task and resemblance to human answers may each matter. None means the same thing. The review therefore changes the opening question from ‘What personality did this chatbot score?’ to ‘What did our procedure actually reveal, and how do we know?’ That question makes AI research more useful precisely because it refuses to confuse a familiar human label with an explanation.
The review does not settle whether every psychological concept could or could not ever apply to artificial systems. It shows that current empirical claims often run ahead of the evidence supplied for them. Better measures, better experiments and clearer limits are the way to learn something real from the systems we have.
What to keep
- Human tests do not transfer automatically to AI systems.
- A score can be a measurement phantom rather than a genuine trait.
- Both construct validity and causal inference need examination.
The nuance
What this story does not let us claim
The argument does not say language models are useless for psychology; it says claims must match the evidence and the test's validity.
Go deeper: concepts and optional reading practice
Reversible cards
Test the concept
Topic assessment
Check whether you can explain the idea, not merely recognize it.
Every answer is grounded in the explanation above. Some questions introduce new cases to test whether you can apply and analyze the ideas, not merely recall them.
Source & scope
From Prompts to Constructs: A Dual-Validity Framework for Large Language Model Research in Psychology. Zhicheng Lin. Annual Review of Psychology, vol. 78 (2027). First published as a Review in Advance on August 10, 2026.
This editorial guide is an independent explanation. Consult the original publication for the studies, references and full context.
Open the original review ↗